Have you ever looked at a chart and wanted to ask it a question? Not run another crosstab — ask it, and have it answer in the words of the people behind the numbers. That is now possible on the study you are running, without inventing a single respondent.
Did You Ever Want to Talk With Your Data?
You are looking at a chart. Segment 2 rates the feature 8.1 and Segment 4 rates it 5.6. The number is right, the gap is significant, and the only thing you actually want to know is why — which is nowhere in the table.
Or it arrives from the other direction.
What kind of label would appeal most to Segment 3, and what would it have to say?
Nobody asked them. It is not in the questionnaire and it will never be in the tables, because the idea did not exist when the questionnaire was written.
Or you are staring at a response pattern that does not sit right.
This group says they want the premium version and then buys the cheap one. Half of them rate the brand highly and would not recommend it. Something is going on in there, and every instrument you have — banner tables, crosstabs, a significance test — can only hand you back more numbers about the thing you already noticed.
Every researcher has had all three.
You have the data. You can see the shape of something in it. And there has never been a way to simply ask — to read between the lines, follow a hunch three questions deep, or find out what these particular people would make of an idea nobody has put to them.
Reading between the lines has always been the expensive part of this job: holding forty variables in mind at once, noticing which of them move together, and saying what that pattern implies about people.
Until recently, the only instrument for it was a very good analyst with a very long weekend.
See Chat With Your Data in Action
Watch this short introduction to see how Chat With Your Data turns existing survey data into deeper, auditable insights.
What Chat With Your Data Is
You pick a segment — or build a subgroup on the spot, such as women 35–54 who already own one — and talk to it.
In plain English.
It answers in that segment’s voice, out of that segment’s real answers. Then a second model immediately reads that answer back against the survey data and tells you how far it went beyond what was actually measured.
The reach comes from a frontier model with hundreds of billions of parameters’ worth of pattern in human language.
What holds comes from your respondents.
The model is allowed to be articulate and imaginative. It is not allowed to be the source.
That distinction matters.
A conventional table can only tell you what people were asked and how they answered. A synthetic respondent can give you an answer to almost anything, but that answer may have no real respondent behind it.
The useful space is between those two extremes: using AI to explore what your real respondents’ answers might imply, while clearly showing when the model has moved beyond what was directly measured.
The Zone Your Tables Cannot Enter
Every structured answer carries one of three labels, and the middle one is the whole point of doing this.
- Anchored — this traces directly to questions these people answered. Your tables are one hundred per cent anchored. That is their virtue, and it is also their ceiling.
- Extrapolated — a reasonable step from what they answered to something they were never asked. This is the reading-between-the-lines zone. It is where new thinking lives, and it is exactly the territory a crosstab cannot enter.
- Imagined — in character, with nothing behind it. It is marked so it is never mistaken for a finding.
Most tools in this space either refuse to leave the first box, in which case they have given you a slower crosstab, or they roam freely in the third and present it as the first.
The useful product is the one that goes a long way into the second and tells you every time it does.
What You Can Actually Do With It
All of this runs against the study you have in the field or in the drawer, in the same session, on the same people.
Interrogate a Segment Like a Respondent
Ask the follow-up the questionnaire did not have room for.
Ask the same question three ways and watch which framing changes the answer — which is itself a finding about how to talk to them.
Talk to Named Individuals, Not Just Aggregates
Real respondents can be drawn either as the most typical members of a subgroup or as the most distinctive.
Each answer tells you which.
That distinction matters because what this segment thinks and what makes this segment different are two different pieces of evidence, and they are easy to confuse.
Run a Focus Group That Could Not Otherwise Be Convened
Put six people from four segments in a room and give them an agenda.
They disagree with each other, in their own terms, out of their own answers.
Ask Them to Picture It
Have a segment describe what they would actually want — and generate the image from their brief, not yours.
That gives you a concept in front of a stakeholder quickly, rather than waiting to brief a designer and develop it from scratch.
Get the Language Back in Their Words
This is not copy written for them, which is what an AI writer does.
It is the language they used: the objection they raise unprompted, the framing that makes them lean in and the one that makes them switch off.
It is the raw material a good copywriter has always wanted and usually had to infer from a handful of depth interviews.
Test the Idea That Arrived After Fieldwork Closed
The Thursday sketch.
You cannot ask 1,800 people about it, but you can ask the segments how it lands, get a marked answer, and decide whether it is worth the cost of asking real people properly.
What That Looks Like: Two Answers Nobody Had Put Together
Here is a simple example from a demonstration study in the television and streaming category.
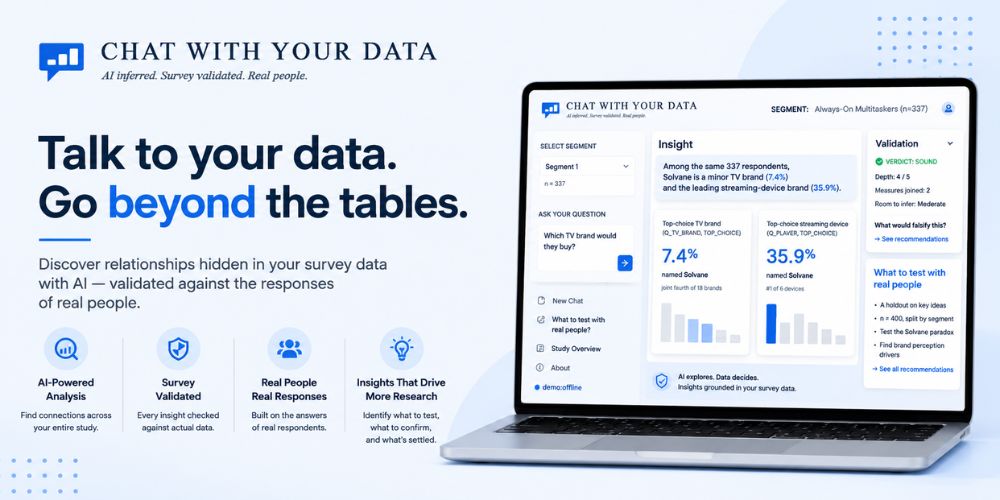
The segment contains 337 people. The study already contained answers to two different questions. They simply lived in different parts of the report.
Asked which TV brand they would choose, 7.4% of the segment picked Solvane.
That made Solvane joint fourth — the kind of number you might easily skip past.
Then came the other question.
Asked which streaming device they would choose, 35.9% of those same 337 people picked Solvane.
This time, Solvane was the clear leader.
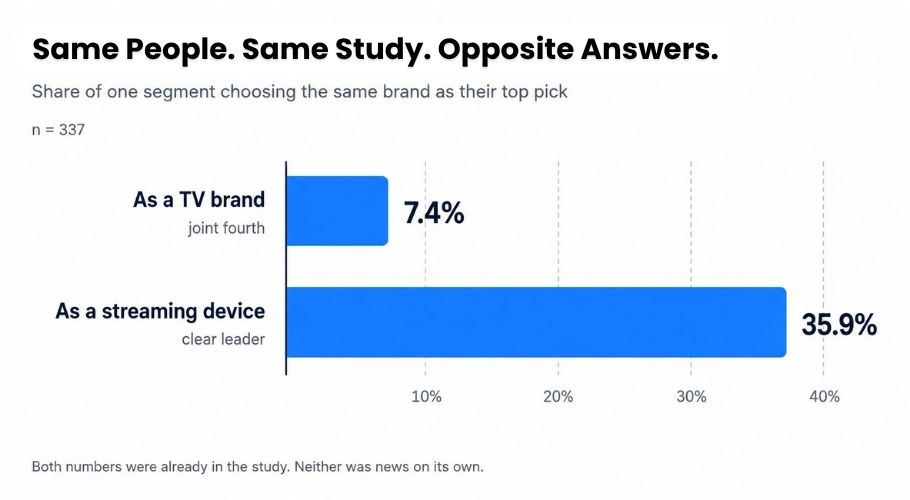
Neither was particularly remarkable on its own. Nobody had put them side by side because they lived in different chapters of the report.
Read together, they say something neither says alone:
This segment will take the brand into the living room as a box, but will not take it as a screen.
That is not simply a brand-preference problem to be fixed with more consideration advertising.
It points towards a different product decision and a different campaign.
The evaluation on that answer was SOUND, with a depth score of 4 out of 5 and three survey questions joined.
Two tables and an argument — and the argument was checked before it reached anybody’s deck.
The point is not that AI found a number that was not there. The numbers were already there. The point is that AI made it possible to ask what those numbers meant together.
Pictures, and the Part Everyone Gets Wrong
AI-generated images create another problem for market researchers.
A beautiful render can easily look like research evidence when it is actually nothing more than an AI-generated interpretation.
So the picture needs to be judged on the part that is actually checkable.
A brief describes something that does not exist yet — a colour, a material, a room, a product shape. None of those things may exist in the survey, so asking whether the visual itself is “supported by the data” would produce an overreach verdict on almost every creative brief.
That tells you nothing.
Instead, the useful question is:
Are the wants behind this picture these people’s own, or has the brief invented a person?
The form — the shape, finish, light, colour or material — is invented by definition.
The wants are claims about your respondents.
“Matte, because I cannot stand fingerprints” is checkable. It either came from their answers or it did not.
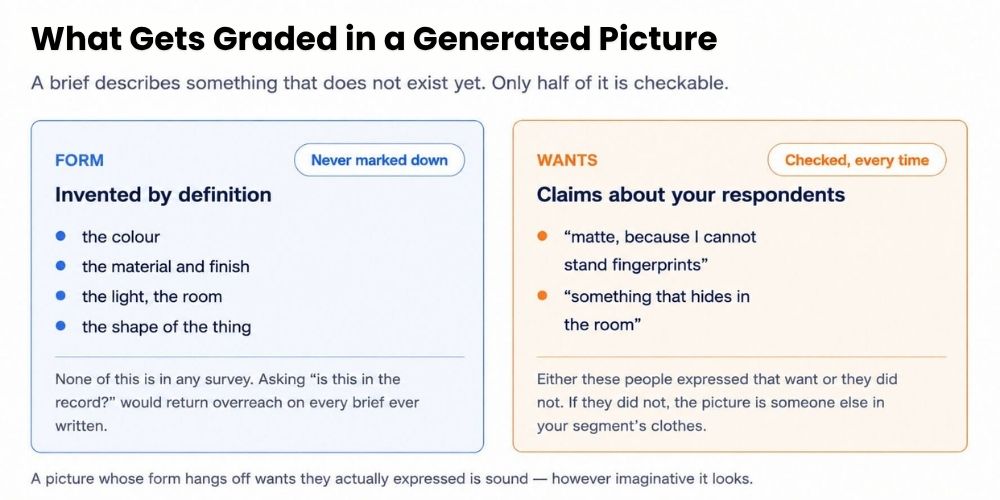
A picture built around a want nobody expressed is something else: somebody else’s idea wearing your segment’s clothes.
And that is exactly the kind of thing that can accidentally be carried into a design review as if it were evidence.
Why You Can Trust an Answer That Went Beyond the Data
Going beyond the tables is only useful if you know how far beyond the data you have gone.
That is why the audit matters.
There are three checks.
First, every structured answer is labelled, and that label is enforced by the application rather than simply claimed by the model.
Cited question IDs are resolved against the dataset. If an answer claims to be anchored but there is no real source question behind it, it is downgraded. Invented citations are stripped.
The model does not grade its own homework.
Second, a separate model audits the answer.
It looks at how much room there was to infer, how many survey questions were joined, the depth of the answer, its plausibility, and whether the overall claim is sound, overreach or contradicted.
It also identifies what would falsify the claim.
Third, the arithmetic is done in arithmetic.
If 41% of a segment chose a brand, then among ten typical members you would expect about four. Five is ordinary.
That counting happens in code before the critic sees it, so the judgement is about the claim rather than a model trying to do mental maths.
And these checks have been tested by deliberately finding where the system could go wrong.
Two defects were particularly useful.
In one case, the most important brand question in the study never reached the model because questions were being selected according to how sharply they split segments. That was a reasonable rule, but it meant the system could overlook the question the researcher actually cared about.
In another, the critic itself initially treated ordinary variation within a group as a contradiction.
Both problems were fixed.
That matters because an audit that has never been challenged is only decoration.
Where the Audit Said Slow Down
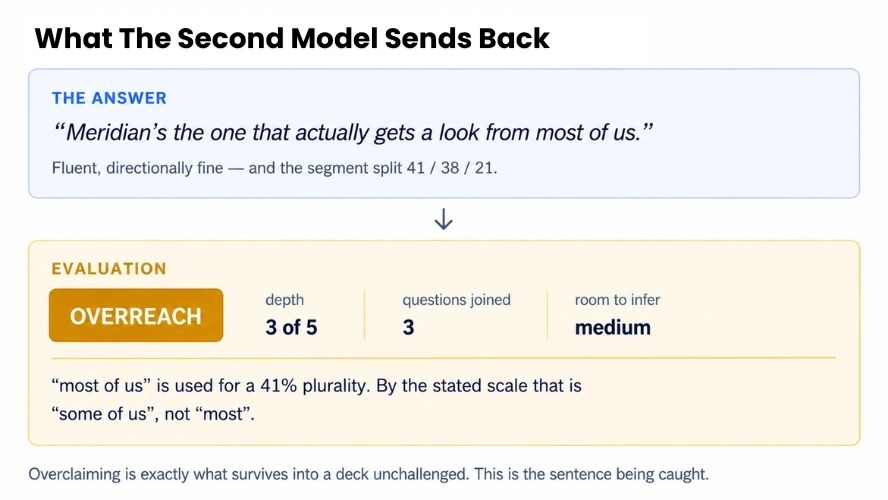
Here is what an actual audit looks like.
Suppose a segment is split 41 / 38 / 21 across three choices.
The generated answer says:
“This brand actually gets a look from most of us.”
The critic returns:
OVERREACH
Why?
Because 41% is a plurality, not “most”.
The answer is directionally reasonable. But it overclaims what the data says.
That distinction matters because fluent language is exactly what can make an overclaim survive into a presentation without anyone noticing.
The same principle applies to other distributions.
A 34 / 30 / 22 / 14 split does not support saying “a firm no from most of us”, either.
But correcting the overclaim does not mean making the answer useless.
A better answer might say:
The group is split almost down the middle. About half think whatever is built into the set will beat a separate box, while the other half think a separate box will beat what is built in. Neither side is winning the argument.
That answer is more cautious, but it still tells you something useful.
In this case, the more interesting observation is that the division itself may not be the story.
The important point is simple:
The system will sometimes overclaim. The difference is that you are told which sentences do it.
From an Idea to Something Worth Commissioning
This is where the process comes back to real market research.
Every audited answer carries the question that would falsify it.
Those questions can be collected into a practical set of hypotheses: claims stated clearly enough that real research can prove them wrong.
They can then be sorted into:
- Worth confirming
- Worth testing
- Already settled — do not commission this
That last category matters.
If your existing study has already answered a question, there is no reason to pay to ask it again.
The purpose of going beyond the tables is therefore not to create an endless stream of AI-generated ideas.
It is to go a long way past the tables, understand exactly how far you went, and come back with a short list of things worth testing with real people.
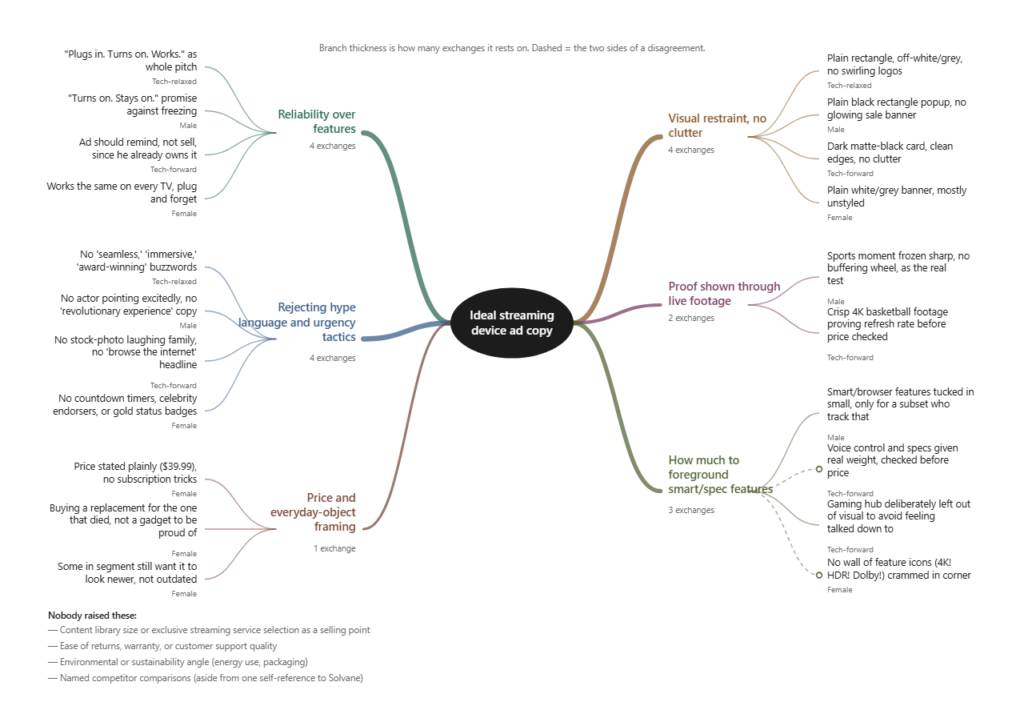
The AI exploration becomes the bridge between the research you already have and the research you may want to commission next.
What It Does Not Do
There are some important boundaries.
- It is not fieldwork. Nothing here substitutes for asking real people something you have not asked them. It tells you which questions may be worth their time.
- Free chat is not validated. It carries a permanent notice saying so. Generated images and their briefs are never presented as measurements.
- Not every interaction is audited. Only structured segment answers on direct questions are audited. Focus-group turns are audited only when that option is switched on.
- Percentages may sometimes differ from your tables. Where the tool works from a sample of records, the displayed percentage can differ from the full-study figure. In the demonstration study, for example, 38.4% appeared against a table figure of 41.5%. That is sampling, stated rather than hidden.
- The critic can be wrong. It is a second opinion, not an oracle.
- People still decide. Researchers decide segment membership, names, interpretation, write-ups and what ultimately gets commissioned.
That last point is important.
AI can help you explore the space between the questions you asked and the questions you wish you had asked.
It does not get to decide what the research means.
See Chat with your Data on Your Own Study
The easiest way to understand this is to use it on your own data.
Bring a segmentation from a study — one currently in the field or one from last year.
You will see your segments in the picker and your questions in the box. Structured answers come back with the survey question IDs behind them, a depth score and an audit verdict.
Then ask it something your tables cannot answer.
That is the whole demonstration.
Screenshots and figures are from the running application on the Solvane Connected Entertainment Segmentation — a demo engagement over real study artefacts.
Segment bases, lifts and every percentage quoted are that study’s own figures, not properties of the product; the persona and audit prose in the demo corpus is composed, and the header reads demo:offline to say so.